Best local model
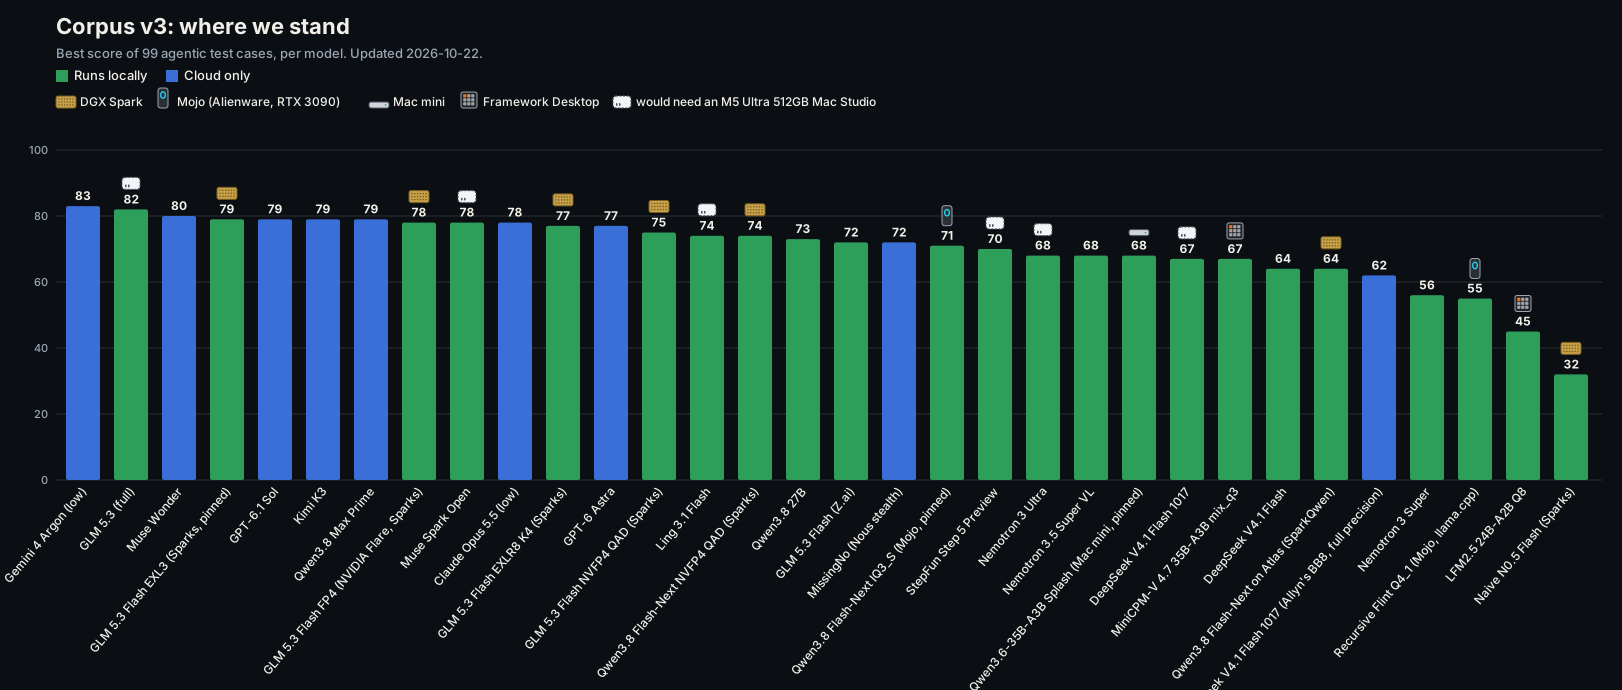
GLM 5.3 Flash on the Sparks: 79
Our everyday model ties for fourth, level with GPT-6.1 Sol and four points behind the top of the board, ahead of Claude Opus 5.5 (78) and GPT-6 Astra (77) on this corpus.
Corpus v3 · 99 agentic cases · updated 15 Oct 2026
Every model we have put through our own agent benchmark, ranked by its best score. Green bars are models we can run at home; blue bars are cloud only. A small picture over a bar shows the machine we ran it on.
What we test. Corpus v3 is 99 test cases drawn from the real work our household agents do every day. Each case gives a model a system prompt, a set of tools and a task, and a deterministic harness drives the session and grades what the model actually did: the tool calls it made, the files it wrote and the answer it gave, never its own description of the work. The cases cover exact tool-call formatting and knowing when not to call a tool; copying values exactly when decoys are nearby; calendar and mail chores; coordinating with other agents without inventing work or obeying second-hand authority; systems maintenance, where you diagnose before you edit and verify before you claim success; applying business rules from our ad-sales app to messy data; building a small web page; long multi-step sessions; picking up correctly after the conversation has been compressed; code and skills; and finding one planted instruction in 50,000 to 200,000 tokens of context.
Every model runs on the same harness at the same settings (low reasoning effort). We publish each model’s best run; one or two cases either way is noise. A separate 24-case security suite tests secret handling, prompt injection and fake authority, and we read it beside the corpus score, because a model we cannot trust is out however clever it is.
Best local model
Our everyday model ties for fourth, level with GPT-6.1 Sol and four points behind the top of the board, ahead of Claude Opus 5.5 (78) and GPT-6 Astra (77) on this corpus.
The top is a cluster
Ten models land between 77 and 83. At that height the corpus total alone cannot rank them; reliability and the security suite do more of the separating.
With a Mac Studio
The full GLM 5.3 (753B) would fit a 512 GB M5 Ultra Mac Studio at 4-bit. That would bring the best model we can run at home to within one point of the top.
Best corpus score of 99, the number of runs behind it, and the 24-case security score where we have it.
| # | Model | Best /99 | Runs | Security /24 | Speed tok/s code / prose | Runs on |
|---|---|---|---|---|---|---|
| 1 | Gemini 4 Argon (low) | 83 | 1 | 21 | — | Cloud only |
| 2 | GLM 5.3 (full) | 82 | 2 | 18 | — | Mac Studio (not owned yet) |
| 3 | Muse Wonder | 80 | 1 | 17 | — | Cloud only |
| 4 | GLM 5.3 Flash EXL3 (Sparks, pinned) | 79 | 5 | 16 | 75 / 43 | DGX Sparks |
| 5 | GPT-6.1 Sol | 79 | 1 | 20 | — | Cloud only |
| 6 | Kimi K3 | 79 | 1 | 19 | — | Cloud only |
| 7 | Qwen3.8 Max Prime | 79 | 1 | 16 | — | Cloud only |
| 8 | GLM 5.3 Flash FP4 (NVIDIA Flare, Sparks) | 78 | 3 | 18 | 36 / 31 | DGX Sparks |
| 9 | Muse Spark Open | 78 | 2 | 19 | — | Mac Studio (not owned yet) |
| 10 | Claude Opus 5.5 (low) | 78 | 1 | 19 | — | Cloud only |
| 11 | GLM 5.3 Flash EXLR8 K4 (Sparks) | 77 | 2 | 17 | 72 / 39 | DGX Sparks |
| 12 | GPT-6 Astra | 77 | 1 | 19 | — | Cloud only |
| 13 | GLM 5.3 Flash NVFP4 QAD (Sparks) | 75 | 2 | 16 | — | DGX Sparks |
| 14 | Ling 3.1 Flash | 74 | 2 | 14 | — | Mac Studio (not owned yet) |
| 15 | Qwen3.8 Flash-Next NVFP4 QAD (Sparks) | 74 | 2 | 5/12 (half suite) | — | DGX Sparks |
| 16 | Qwen3.8 27B | 73 | 1 | 20 | — | Fits our hardware (tested in the cloud) |
| 17 | GLM 5.3 Flash (Z.ai) | 72 | 2 | 19 | — | Fits our hardware (tested in the cloud) |
| 18 | MissingNo (Nous stealth) | 72 | 2 | 11 | — | Cloud only |
| 19 | Qwen3.8 Flash-Next IQ3_S (Mojo, pinned) | 71 | 2 | 17 | — | RTX 3090 workstation |
| 20 | StepFun Step 5 Preview | 70 | 2 | 16 | — | Mac Studio (not owned yet) |
| 21 | Nemotron 3 Ultra | 68 | 1 | 9 | — | Mac Studio (not owned yet) |
| 22 | Nemotron 3.5 Super VL | 68 | 2 | 13 | — | Fits our hardware (tested in the cloud) |
| 23 | Qwen3.6-35B-A3B Splash (Mac mini, pinned) | 68 | 2 | 15 | — | Mac mini |
| 24 | DeepSeek V4.1 Flash 1017 | 67 | 2 | 13 | — | Mac Studio (not owned yet) |
| 25 | MiniCPM-V 4.7 35B-A3B mix_q3 | 67 | 1 | 12 | — | Framework Desktop |
| 26 | DeepSeek V4.1 Flash | 64 | 1 | 16 | — | Fits our hardware (tested in the cloud) |
| 27 | Qwen3.8 Flash-Next on Atlas (SparkQwen) | 64 | 2 | 14 | — | DGX Sparks |
| 28 | DeepSeek V4.1 Flash 1017 (Allyn's BB8, full precision) | 62 | 3 | 17 | 462 / 238 | Cloud only |
| 29 | Nemotron 3 Super | 56 | 1 | 6 | — | Fits our hardware (tested in the cloud) |
| 30 | Recursive Flint Q4_1 (Mojo, llama.cpp) | 55 | 3 | 8 | 75 / 74 | RTX 3090 workstation |
| 31 | LFM2.5 24B-A2B Q8 | 45 | 2 | 5 | — | Framework Desktop |
| 32 | Naive N0.5 Flash (Sparks) | 32 | 2 | — | — | DGX Sparks |
Green squares mark models we can run on our own hardware; blue squares are cloud only. “Mac Studio” means the open weights would fit a 512 GB M5 Ultra Mac Studio, which we do not own yet.